 ROS Index

|
isaac_ros_dnn_stereo_depth repositoryisaac_ros_dnn_stereo_decoder isaac_ros_ess isaac_ros_ess_models_install isaac_ros_foundationstereo isaac_ros_foundationstereo_models_install |
ROS Distro
|
Repository Summary
| Description | |
| Checkout URI | https://github.com/nvidia-isaac-ros/isaac_ros_dnn_stereo_depth.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-09-22 |
| Dev Status | UNKNOWN |
| Released | UNRELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| isaac_ros_dnn_stereo_decoder | 5.0.0 |
| isaac_ros_ess | 5.0.0 |
| isaac_ros_ess_models_install | 5.0.0 |
| isaac_ros_foundationstereo | 5.0.0 |
| isaac_ros_foundationstereo_models_install | 5.0.0 |
README
Isaac ROS DNN Stereo Depth
NVIDIA-accelerated, deep learned stereo disparity estimation
Webinar Available
Learn how to use this package by watching our on-demand webinar: Using ML Models in ROS 2 to Robustly Estimate Distance to Obstacles
Overview
Deep Neural Network (DNN)–based stereo models have become essential for depth estimation because they overcome many of the fundamental limitations of classical and geometry-based stereo algorithms.
Traditional stereo matching relies on explicitly finding pixel correspondences between left and right images using handcrafted features. While effective in well-textured, ideal conditions, these approaches often fail in “ill-posed” regions such as areas with reflections, specular highlights, texture-less surfaces, repetitive patterns, occlusions, or even minor camera calibration errors. In such cases, classical algorithms may produce incomplete or inaccurate depth maps, or be forced to discard information entirely, especially when context-dependent filtering is not possible.
DNN-based stereo methods learn rich, hierarchical feature representations and context-aware matching costs directly from data. These models leverage semantic understanding and global scene context to infer depth, even in challenging environments where traditional correspondence measures break down. Through training, DNNs can implicitly account for real-world imperfections such as:
- calibration errors
- exposure differences
- hardware noise
Training increases DNN’s ability to recognize and handle difficult regions like reflections or transparent surfaces. This results in more robust, accurate, and dense depth predictions.
These advances are critical for robotics and autonomous systems, enabling applications where both speed and accuracy of depth perception are essential, such as:
- precise robotic arm manipulation
- reliable obstacle avoidance and navigation
- robust target tracking in dynamic or cluttered environments
DNN-based stereo methods consistently outperform classical techniques, making them the preferred choice for modern depth perception tasks.
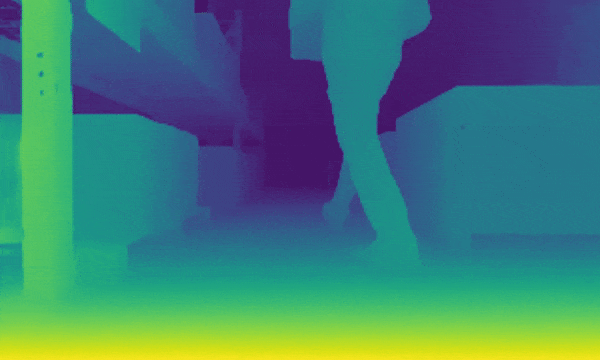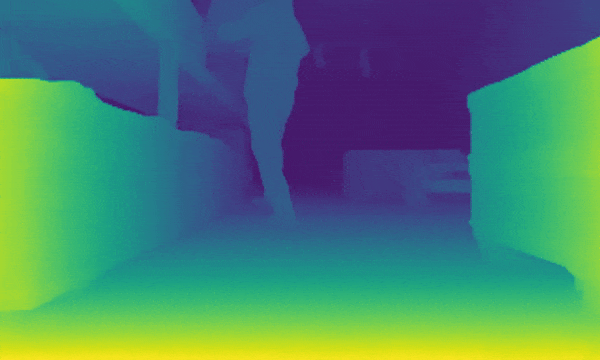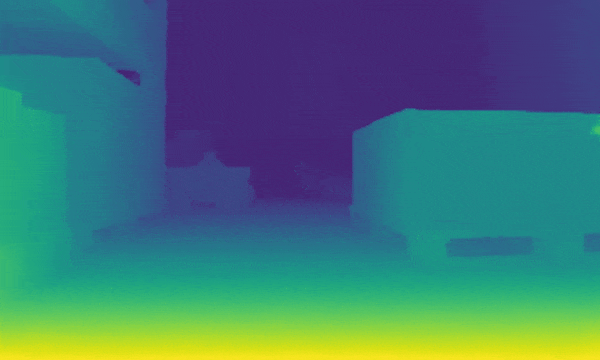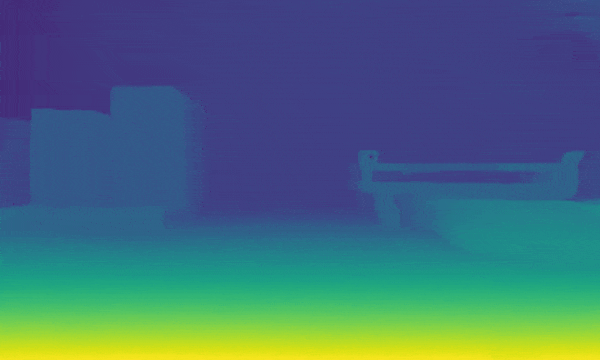
The superiority of DNN-based stereo methods is clearly demonstrated in the figure above where we compare the output from a classical stereo algorithm, SGM, with DNN-based methods, ESS, and FoundationStereo.
SGM produces a very noisy and error-prone disparity map, while ESS and FoundationStereo produce much smoother and more accurate disparity maps. A closer look reveals that FoundationStereo produces the most accurate map because it is better at handling the plant in the distance and the railings on the left with smoother estimates. Overall, you can see that FoundationStereo is better than ESS, and better than SGM, in terms of accuracy and quality.
DNN‐based stereo systems begin by passing the left and right images through shared Convolutional backbones to extract multi‐scale feature maps that encode both texture and semantic information. These feature maps are then compared across potential disparities by constructing a learnable cost volume, which effectively represents the matching likelihood of each pixel at different disparities. Successive 3D Convolutional (or 2D convolution + aggregation) stages then regularize and refine this cost volume, integrating strong local cues—like edges and textures—and global scene context—such as object shapes and layout priors—to resolve ambiguities. Finally, a soft‐argmax or classification layer converts the refined cost volume into a dense disparity map, often followed by lightweight refinement modules that enforce sub-pixel accuracy and respect learned priors (for example, smoothness within objects, sharp transitions at boundaries), yielding a coherent estimate that gracefully handles challenging scenarios where classical algorithms falter.
ROS 2 Native rosidl::Buffer Acceleration
This package uses rosidl::Buffer, a feature built into ROS 2 Lyrical, to
avoid unnecessary copies of large payloads between CPU and accelerator
memory. The CUDA buffer backend builds on this native ROS 2 feature to provide
CUDA memory storage and transport. Most applications can use standard ROS
messages and conversion packages without depending directly on a buffer
backend. See rosidl::Buffer and Buffer Backends for details.
Performance
| Sample Graph |
Input Size |
AGX Thor T5000 |
AGX Thor T4000 |
AGX Orin |
Orin Nano Super 8GB |
DGX Spark |
x86_64 w/ RTX 5090 |
x86_64 w/ RTX 5070 |
|---|---|---|---|---|---|---|---|---|
|
DNN Stereo Disparity Graph Full |
576p |
99.8 fps 12 ms @ 30Hz |
77.1 fps 16 ms @ 30Hz |
66.5 fps 17 ms @ 30Hz |
34.8 fps 30 ms @ 30Hz |
102 fps 10 ms @ 30Hz |
350 fps 3.2 ms @ 30Hz |
233 fps 4.7 ms @ 30Hz |
|
DNN Stereo Disparity Graph Light |
288p |
203 fps 6.7 ms @ 30Hz |
161 fps 8.3 ms @ 30Hz |
75.5 fps 24 ms @ 30Hz |
82.2 fps 13 ms @ 30Hz |
192 fps 5.4 ms @ 30Hz |
350 fps 2.5 ms @ 30Hz |
350 fps 3.0 ms @ 30Hz |
Documentation
Please visit the Isaac ROS Documentation to learn how to use this repository.
Packages
File truncated at 100 lines see the full file
CONTRIBUTING
Isaac ROS Contribution Rules
Any contribution that you make to this repository will be under the Apache 2 License, as dictated by that license:
5. Submission of Contributions. Unless You explicitly state otherwise, any Contribution intentionally submitted for inclusion in the Work by You to the Licensor shall be under the terms and conditions of this License, without any additional terms or conditions. Notwithstanding the above, nothing herein shall supersede or modify the terms of any separate license agreement you may have executed with Licensor regarding such Contributions.
Contributors must sign-off each commit by adding a Signed-off-by: ...
line to commit messages to certify that they have the right to submit
the code they are contributing to the project according to the
Developer Certificate of Origin (DCO).
|
|
isaac_ros_dnn_stereo_depth repositoryisaac_ros_dnn_stereo_decoder isaac_ros_ess isaac_ros_ess_models_install isaac_ros_foundationstereo isaac_ros_foundationstereo_models_install |
ROS Distro
|
Repository Summary
| Description | |
| Checkout URI | https://github.com/nvidia-isaac-ros/isaac_ros_dnn_stereo_depth.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-09-22 |
| Dev Status | UNKNOWN |
| Released | UNRELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| isaac_ros_dnn_stereo_decoder | 5.0.0 |
| isaac_ros_ess | 5.0.0 |
| isaac_ros_ess_models_install | 5.0.0 |
| isaac_ros_foundationstereo | 5.0.0 |
| isaac_ros_foundationstereo_models_install | 5.0.0 |
README
Isaac ROS DNN Stereo Depth
NVIDIA-accelerated, deep learned stereo disparity estimation
Webinar Available
Learn how to use this package by watching our on-demand webinar: Using ML Models in ROS 2 to Robustly Estimate Distance to Obstacles
Overview
Deep Neural Network (DNN)–based stereo models have become essential for depth estimation because they overcome many of the fundamental limitations of classical and geometry-based stereo algorithms.
Traditional stereo matching relies on explicitly finding pixel correspondences between left and right images using handcrafted features. While effective in well-textured, ideal conditions, these approaches often fail in “ill-posed” regions such as areas with reflections, specular highlights, texture-less surfaces, repetitive patterns, occlusions, or even minor camera calibration errors. In such cases, classical algorithms may produce incomplete or inaccurate depth maps, or be forced to discard information entirely, especially when context-dependent filtering is not possible.
DNN-based stereo methods learn rich, hierarchical feature representations and context-aware matching costs directly from data. These models leverage semantic understanding and global scene context to infer depth, even in challenging environments where traditional correspondence measures break down. Through training, DNNs can implicitly account for real-world imperfections such as:
- calibration errors
- exposure differences
- hardware noise
Training increases DNN’s ability to recognize and handle difficult regions like reflections or transparent surfaces. This results in more robust, accurate, and dense depth predictions.
These advances are critical for robotics and autonomous systems, enabling applications where both speed and accuracy of depth perception are essential, such as:
- precise robotic arm manipulation
- reliable obstacle avoidance and navigation
- robust target tracking in dynamic or cluttered environments
DNN-based stereo methods consistently outperform classical techniques, making them the preferred choice for modern depth perception tasks.
The superiority of DNN-based stereo methods is clearly demonstrated in the figure above where we compare the output from a classical stereo algorithm, SGM, with DNN-based methods, ESS, and FoundationStereo.
SGM produces a very noisy and error-prone disparity map, while ESS and FoundationStereo produce much smoother and more accurate disparity maps. A closer look reveals that FoundationStereo produces the most accurate map because it is better at handling the plant in the distance and the railings on the left with smoother estimates. Overall, you can see that FoundationStereo is better than ESS, and better than SGM, in terms of accuracy and quality.
DNN‐based stereo systems begin by passing the left and right images through shared Convolutional backbones to extract multi‐scale feature maps that encode both texture and semantic information. These feature maps are then compared across potential disparities by constructing a learnable cost volume, which effectively represents the matching likelihood of each pixel at different disparities. Successive 3D Convolutional (or 2D convolution + aggregation) stages then regularize and refine this cost volume, integrating strong local cues—like edges and textures—and global scene context—such as object shapes and layout priors—to resolve ambiguities. Finally, a soft‐argmax or classification layer converts the refined cost volume into a dense disparity map, often followed by lightweight refinement modules that enforce sub-pixel accuracy and respect learned priors (for example, smoothness within objects, sharp transitions at boundaries), yielding a coherent estimate that gracefully handles challenging scenarios where classical algorithms falter.
ROS 2 Native rosidl::Buffer Acceleration
This package uses rosidl::Buffer, a feature built into ROS 2 Lyrical, to
avoid unnecessary copies of large payloads between CPU and accelerator
memory. The CUDA buffer backend builds on this native ROS 2 feature to provide
CUDA memory storage and transport. Most applications can use standard ROS
messages and conversion packages without depending directly on a buffer
backend. See rosidl::Buffer and Buffer Backends for details.
Performance
| Sample Graph |
Input Size |
AGX Thor T5000 |
AGX Thor T4000 |
AGX Orin |
Orin Nano Super 8GB |
DGX Spark |
x86_64 w/ RTX 5090 |
x86_64 w/ RTX 5070 |
|---|---|---|---|---|---|---|---|---|
|
DNN Stereo Disparity Graph Full |
576p |
99.8 fps 12 ms @ 30Hz |
77.1 fps 16 ms @ 30Hz |
66.5 fps 17 ms @ 30Hz |
34.8 fps 30 ms @ 30Hz |
102 fps 10 ms @ 30Hz |
350 fps 3.2 ms @ 30Hz |
233 fps 4.7 ms @ 30Hz |
|
DNN Stereo Disparity Graph Light |
288p |
203 fps 6.7 ms @ 30Hz |
161 fps 8.3 ms @ 30Hz |
75.5 fps 24 ms @ 30Hz |
82.2 fps 13 ms @ 30Hz |
192 fps 5.4 ms @ 30Hz |
350 fps 2.5 ms @ 30Hz |
350 fps 3.0 ms @ 30Hz |
Documentation
Please visit the Isaac ROS Documentation to learn how to use this repository.
Packages
File truncated at 100 lines see the full file
CONTRIBUTING
Isaac ROS Contribution Rules
Any contribution that you make to this repository will be under the Apache 2 License, as dictated by that license:
5. Submission of Contributions. Unless You explicitly state otherwise, any Contribution intentionally submitted for inclusion in the Work by You to the Licensor shall be under the terms and conditions of this License, without any additional terms or conditions. Notwithstanding the above, nothing herein shall supersede or modify the terms of any separate license agreement you may have executed with Licensor regarding such Contributions.
Contributors must sign-off each commit by adding a Signed-off-by: ...
line to commit messages to certify that they have the right to submit
the code they are contributing to the project according to the
Developer Certificate of Origin (DCO).